On-premise Medallion Lakehouse
ActiveA full lakehouse that runs entirely on a laptop: Bronze, Silver and Gold with tests and lineage, depending on no cloud. Useful both for learning the architecture and for testing transformations before taking them to production.
- Role
- Author
- Period
- 2026
The problem
Learning or evaluating a lakehouse architecture usually starts with a cloud account, a cluster billed by the hour and an invoice that grows while you experiment. That makes being wrong expensive — which is precisely what you need to be able to do while learning.
The same problem shows up in daily work: testing whether a transformation works shouldn’t require occupying a shared environment or waiting for one to free up.
The solution
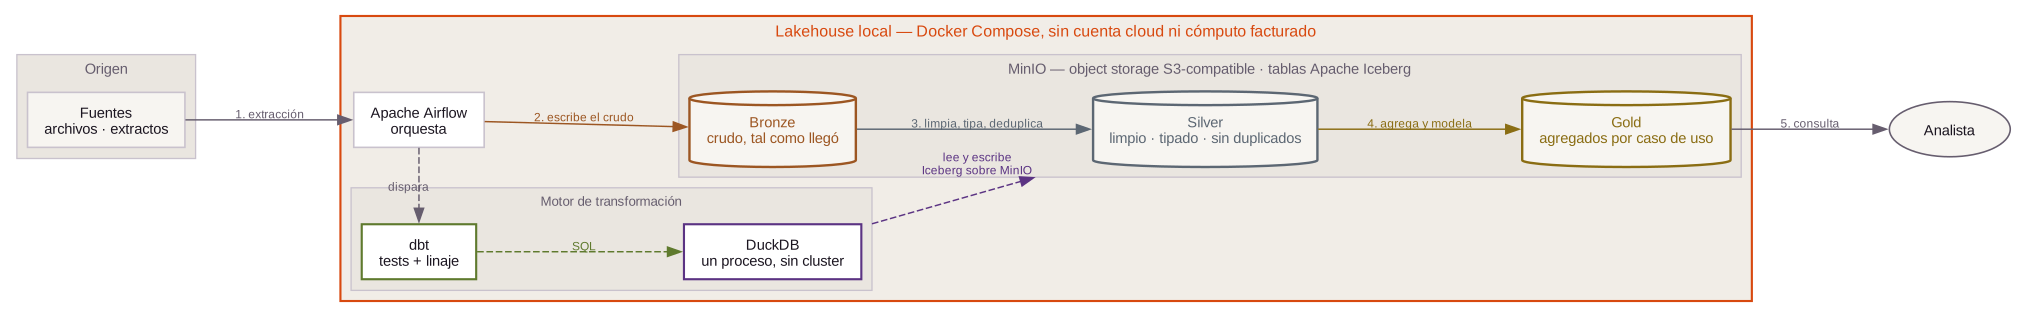
A medallion lakehouse that is 100% reproducible locally, brought up with Docker Compose. Each cloud piece is replaced by an equivalent that runs on the machine, keeping the same interfaces:
| Role | In the cloud | Here |
|---|---|---|
| Object storage | S3 / ADLS | MinIO (S3-compatible) |
| Query engine | Spark / Snowflake | DuckDB |
| Table format | Delta / Iceberg | Apache Iceberg |
| Orchestration | Managed Airflow | Apache Airflow |
| Transformation | dbt | dbt |
MinIO speaking the S3 protocol is what makes the exercise worthwhile: the code that reads and writes doesn’t know it isn’t in the cloud, so what you learn and what you test carries over.
Medallion architecture
architecture/lakehouse-medallion/.The flow follows the three classic layers:
Bronze — raw ingestion, exactly as it arrived. Uncleaned, untyped, undeduplicated. It is the record of what actually came in, and it makes it possible to reprocess everything if a rule changes later.
Silver — clean, typed and conformed data. Duplicates are resolved here, formats normalized and quality rules applied.
Gold — consumption-ready models, aggregated and shaped for the use case.
dbt handles Silver-to-Gold transformations declaratively, with tests over the assumptions that matter and lineage derived automatically from dependencies between models. Airflow orchestrates the whole thing.
Why DuckDB
For volumes that fit on one machine, DuckDB does the work of a distributed engine without the operational cost of being one. There is no cluster to size, no startup time and no inter-node coordination: it is a process that reads Parquet and Iceberg and answers.
The limit is real and worth stating — this does not replace Spark when the data doesn’t fit on a laptop. But a large share of data engineering work happens below that threshold, and there distributed complexity is paid for without getting anything back.
What it solves in practice
- Iterating at no cost. Try a transformation, break it, roll back and repeat without consuming billed compute.
- Reproducibility. The whole environment is declared; it comes up identically on any machine.
- Teaching the architecture. The medallion pattern is far easier to grasp when you can see each layer and break it by hand.
Status
In development. It is the local counterpart to the medallion architectures running in production on Databricks and AWS.